Investigate a risky sign-in
Identity and firewall logs correlated into one triage decision: containment only if the evidence justifies it.
SECURITY · SPLUNK · ENTRA · FIREWALL
Gyr operates the systems you already own, correlates evidence across every modality at machine speed, and returns documented, reproducible findings. On your hardware. Inside your perimeter. Under your rules.
The estate stays exactly where it is. Your SIEM keeps its data, your endpoint platform keeps its telemetry. Gyr sits above what you own. It never asks you to re-platform.
Every system is reached through a governed connector bound to its own scoped, read-only service account. An unknown system is a hard error, never a silent pass-through.
Analysis runs in isolated chambers: each boundary with its own runtime, credentials and working data. Validated procedures accumulate as reusable playbooks.
Documented verdicts, written reports, scheduled briefs. Each carries the exact queries and evidence to reproduce it, recorded in an immutable ledger.
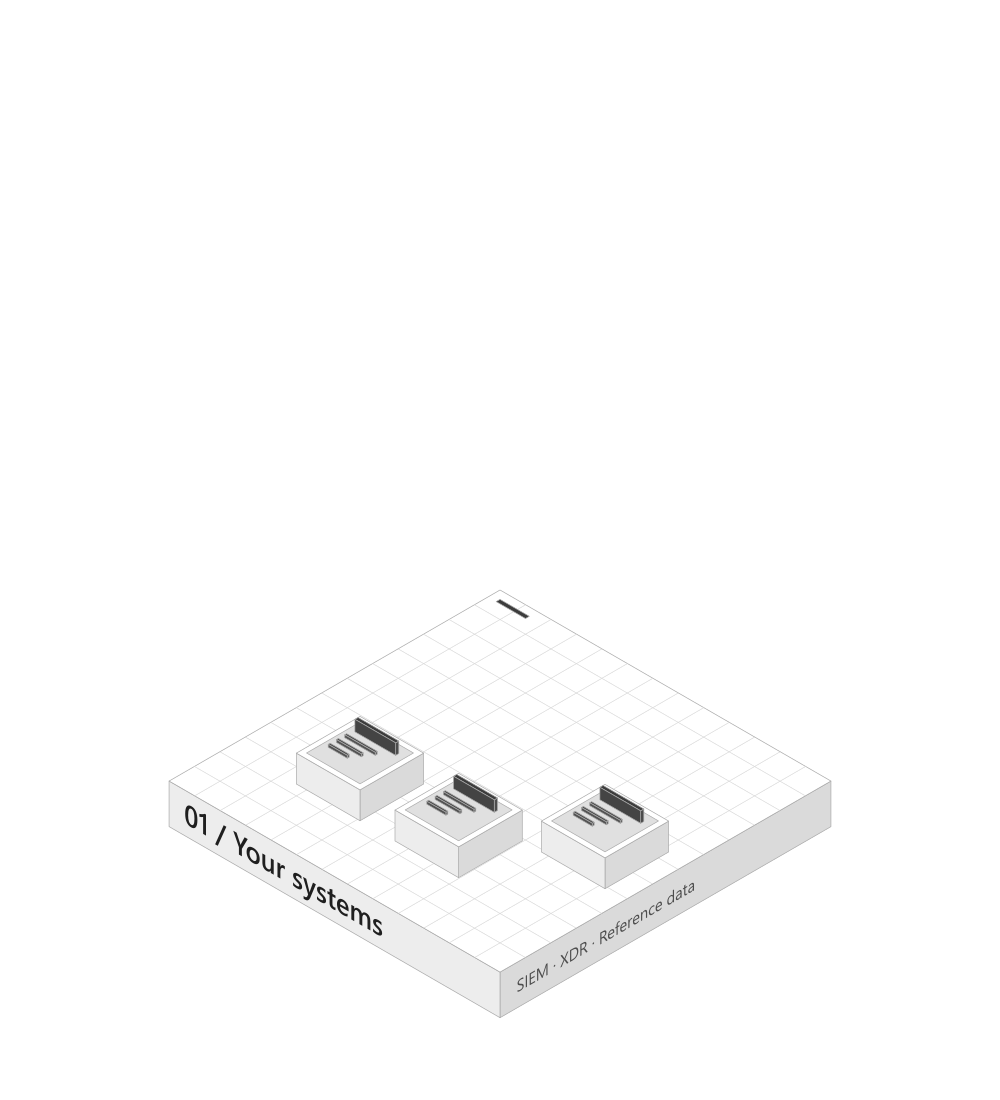
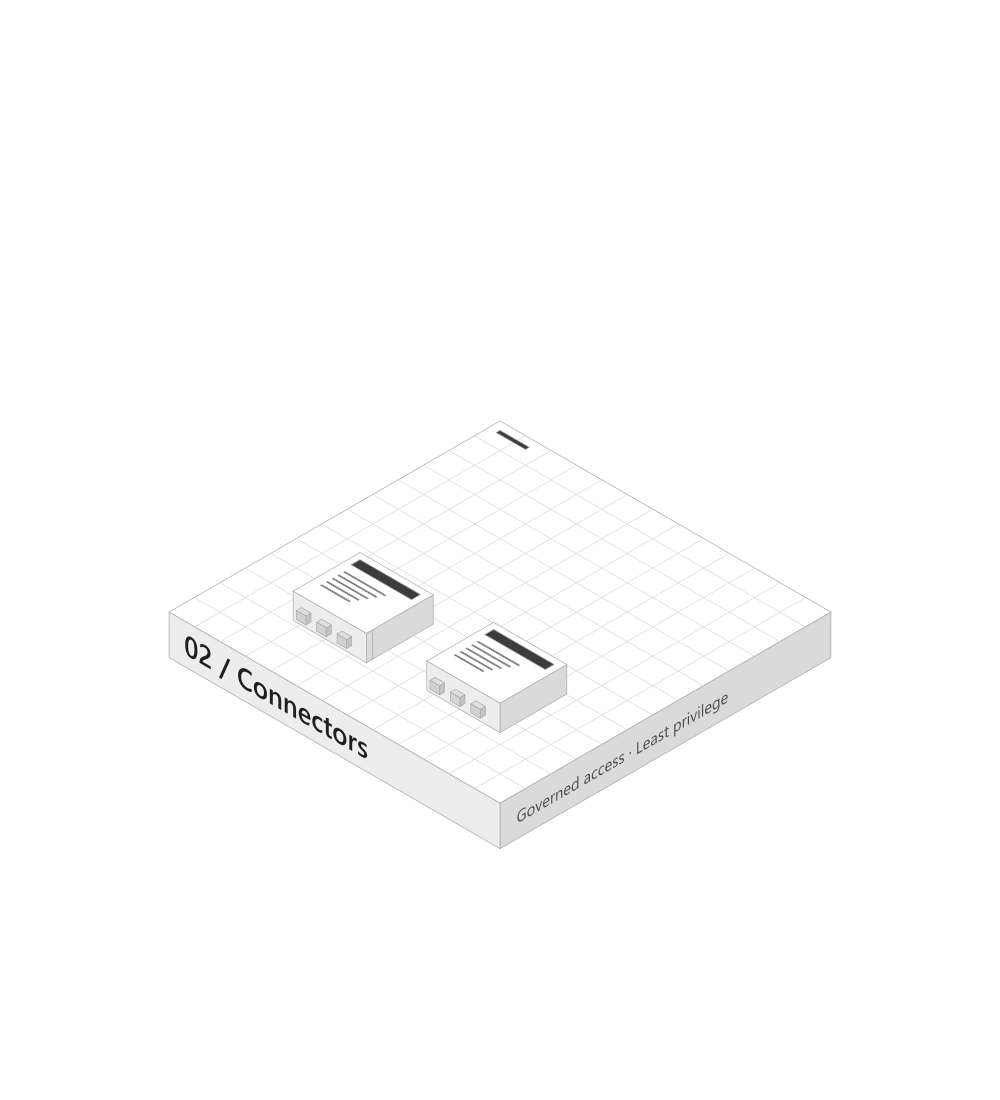
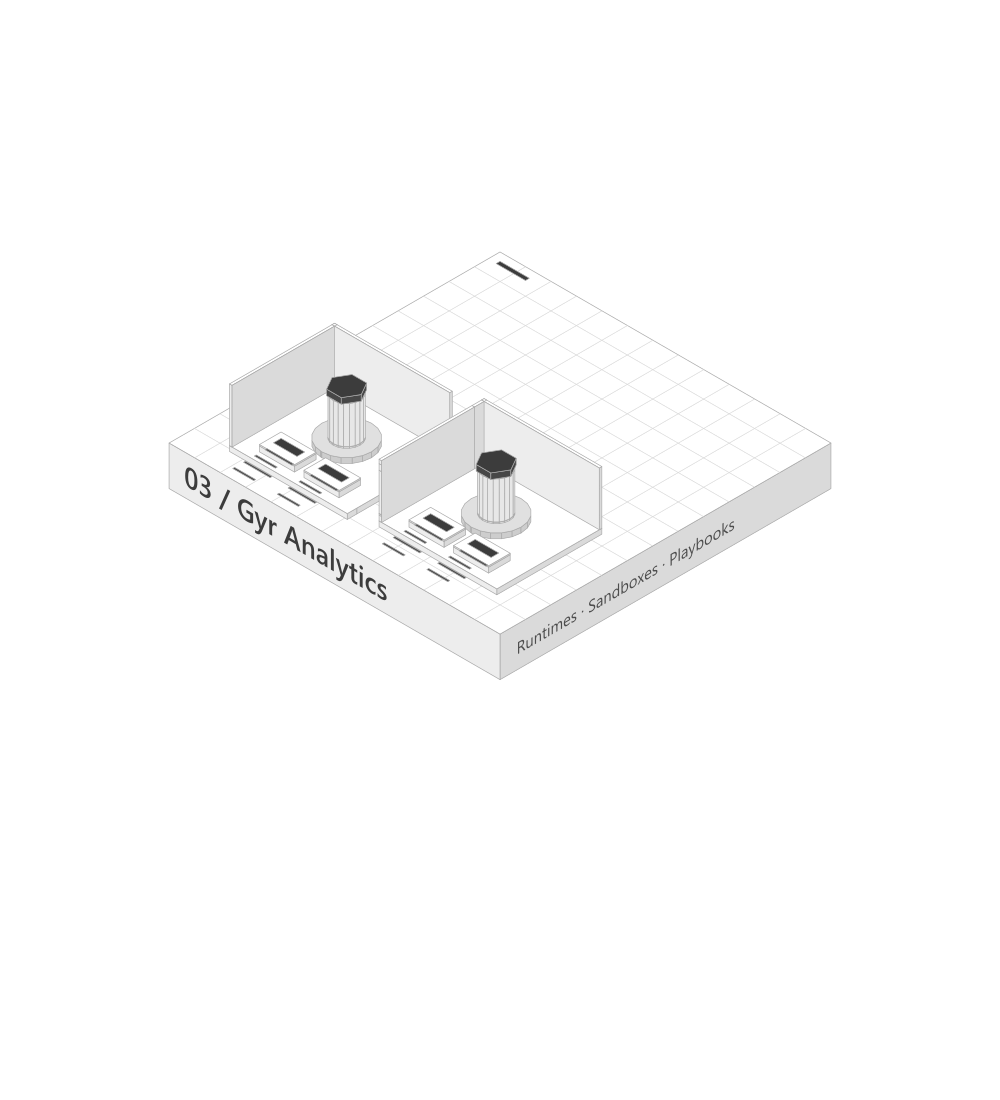
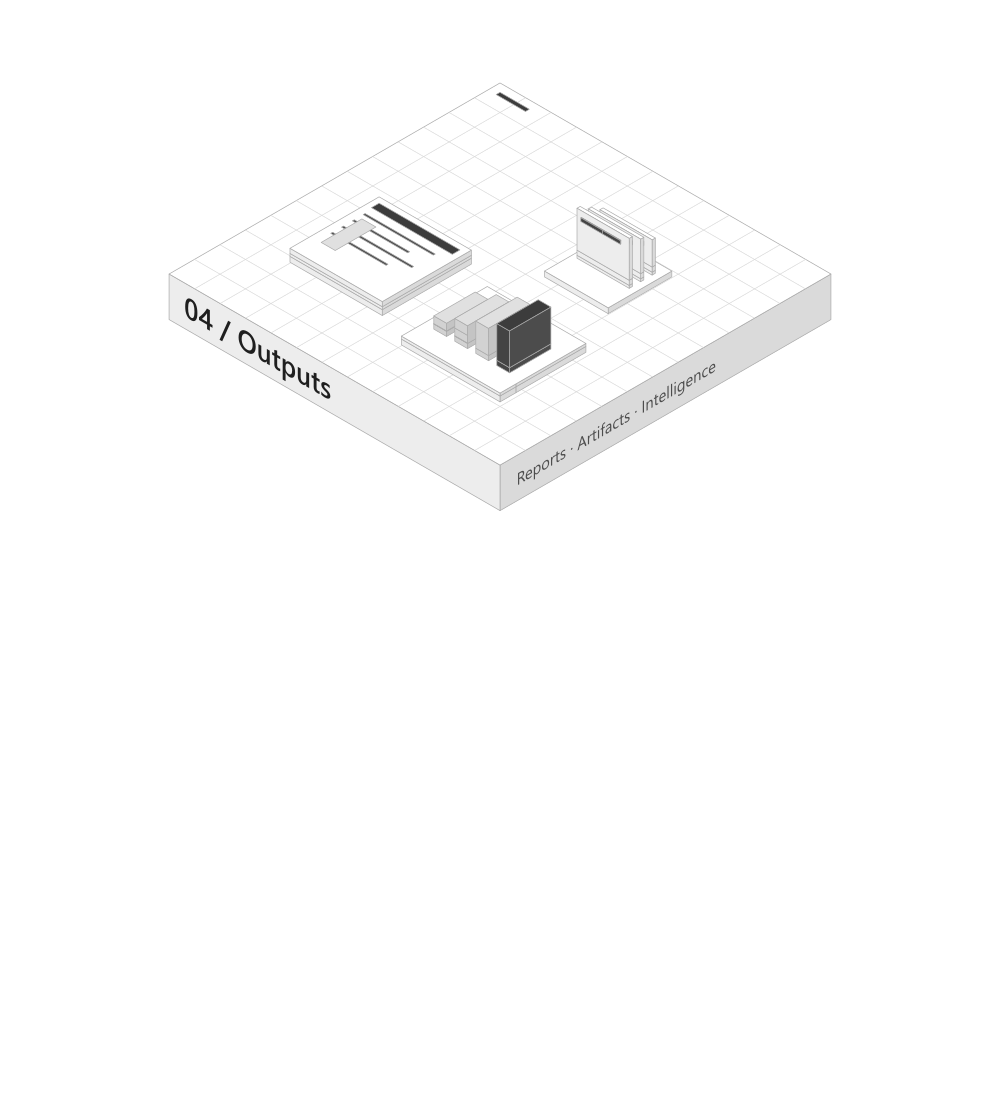
Gyr turns the expertise locked in your teams into capacity you can point anywhere: any domain, any question, on the systems you already own. Every result documented and reproducible.
Identity and firewall logs correlated into one triage decision: containment only if the evidence justifies it.
Can checkout-prod survive a zone outage? Placement and health compared, then the smallest resilience change named before launch.
Disk growth, OS errors and backup status correlated before the business peak: a clear window for action, charted.
Who has production admin access, are reviews current, do changes have approvals? Evidence gaps visible before sign-off.
Billed cost, 14-day utilization and ownership cross-checked; estimates kept separate from approved changes.
WAN load, firewall traffic and interface errors compared; a measured change that protects business traffic, charted.
Security, Cloud and FINOPS delegated in parallel, findings reconciled: one go/no-go with named blockers and owners.
 SPLUNK
 ELASTIC
 DEFENDER
 QRADAR
 AZURE
Reach an evidence-backed triage decision and avoid unnecessary containment. Less analyst effort, fewer unnecessary account disruptions.
Analyst minutes per resolved alertFind a failure risk that healthy-instance metrics alone miss. Lower expected outage loss, less manual readiness analysis.
Services passing a zone-failure testMeasure the time available to act before storage exhaustion. Planned work instead of emergency response, fewer capacity incidents.
Capacity incidents per service-monthSurface overdue reviews and trace approvals to changes. Less evidence-collection effort and audit rework.
Hours per accepted evidence packageIdentify spend that may be removed without affecting production. Lower cloud charges after approved changes.
Verified net monthly savingsPinpoint the traffic driving congestion and propose a measured change. Less troubleshooting, potentially defer a circuit upgrade.
ERP p95 latency in the busy windowA briefing walks the platform against your constraints, then works a real alert end to end through a governed connector. Nothing leaves the room.